Your Reddit RSS feed stops on November 13. Here's what still works
Reddit switches off RSS on November 13 and says there's no replacement for most readers. Some of your feeds can be saved, some can't. Here's how to tell them apart, and a short script for the ones you can keep.
If you follow a few subreddits in a feed reader, you have until November 13. That's the day Reddit stops serving RSS. Every .rss link you have for a subreddit, a search, a user or a thread stops getting new posts, and depending on your reader you'll either see an error or simply nothing new, ever again.
Reddit said so on September 30 in r/modnews, and the post closes on a line that reads a little like a eulogy: "RSS has been a beloved part of the open web for a long time, and we're grateful to everyone who used it to stay connected to Reddit." The sentence right before it is the one that matters if you don't moderate anything: "If you use RSS for feeds outside of a community you moderate, there is no replacement."
That's true for some of your feeds and not for others. A subreddit's new posts can be rebuilt in an evening. Search, user and comment feeds mostly can't. So the useful thing to do this week is sort them.
Why Reddit is doing it
Reddit's stated reason is that RSS "is now a common surface for large-scale scraping and automated abuse." RSS was the last way to read Reddit without logging in or asking permission, and it's being closed along with everything else on the same schedule. Reddit's developer changelog and its r/redditdev announcement give the dates:
| Date | What happens |
|---|---|
| October 31, 2026 | New requests for public API access stop |
| November 13, 2026 | RSS feeds stop |
| January 12, 2027 | API access starts closing for unregistered apps |
| March 2027 | Remaining public API access ends |
Moderators get a way out. Reddit is pointing mod teams that used RSS for alerts to a Devvit app called Discord Relay. Everyone else reading communities they don't run is on their own.
Moving to Feedly won't save you
For a few weeks the standard advice was to move your subreddits into Feedly, which read Reddit through its API rather than RSS. In early October Feedly's own staff were telling people those sources would keep working. They didn't.
On October 31 John Brayton, who makes the Unread reader app, wrote that Reddit had cut off Feedly's API access and ended its contract. A Feedly support reply quoted in the BazQux forum puts it plainly: the integration "stopped working because Reddit ended the access it depended on," and the team doesn't expect it back.
If your Reddit sources in Feedly stopped updating in October, that's why. Nothing is wrong with your account.
Check each Reddit RSS feed URL
Open your reader's subscription list and search it for reddit.com. Every Reddit feed is one of five shapes:
| Your feed URL looks like | What it gave you | After November 13 |
|---|---|---|
reddit.com/r/NAME/.rss or /r/NAME/new/.rss
| A community's posts | Can be rebuilt (below) |
reddit.com/search.rss?q=...
| Every post matching a word, anywhere on Reddit | No direct replacement |
reddit.com/user/NAME/.rss
| One person's posts | No direct replacement |
reddit.com/r/NAME/comments/.rss
| A community's newest comments | No direct replacement |
reddit.com/r/NAME/comments/ID/.rss
| Replies on one thread | No direct replacement |
For the four that can't be rebuilt, the options are small, but they're real:
Search feeds. If you care about the topic more than the fact that it's on Reddit, follow it somewhere else. A Google News search feed covers news, hnrss turns Hacker News into feeds, and many communities have a smaller twin on Lemmy with a working feed, like lemmy.world's selfhosted.
User feeds. Follow the person in the Reddit app, or wherever else they write.
Comment feeds. Read the thread on Reddit. If you moderate the community, look at the Devvit tools Reddit is offering mod teams.
Anything you'd hate to lose. Save it before the 13th. Once the feed stops, it stops.
Keep a subreddit in your reader
A subreddit feed did one simple job: show me each new post once, with its title, link and time. That list still exists on the community's public page, the same posts any logged-out visitor sees. You can read it and write it back out as a feed.
We make Upscrape, so this is how we'd do it, with our Reddit posts endpoint. It reads a community's public listing and returns it as JSON, with no Reddit account and no Reddit API key on your side.
We tried it on r/selfhosted
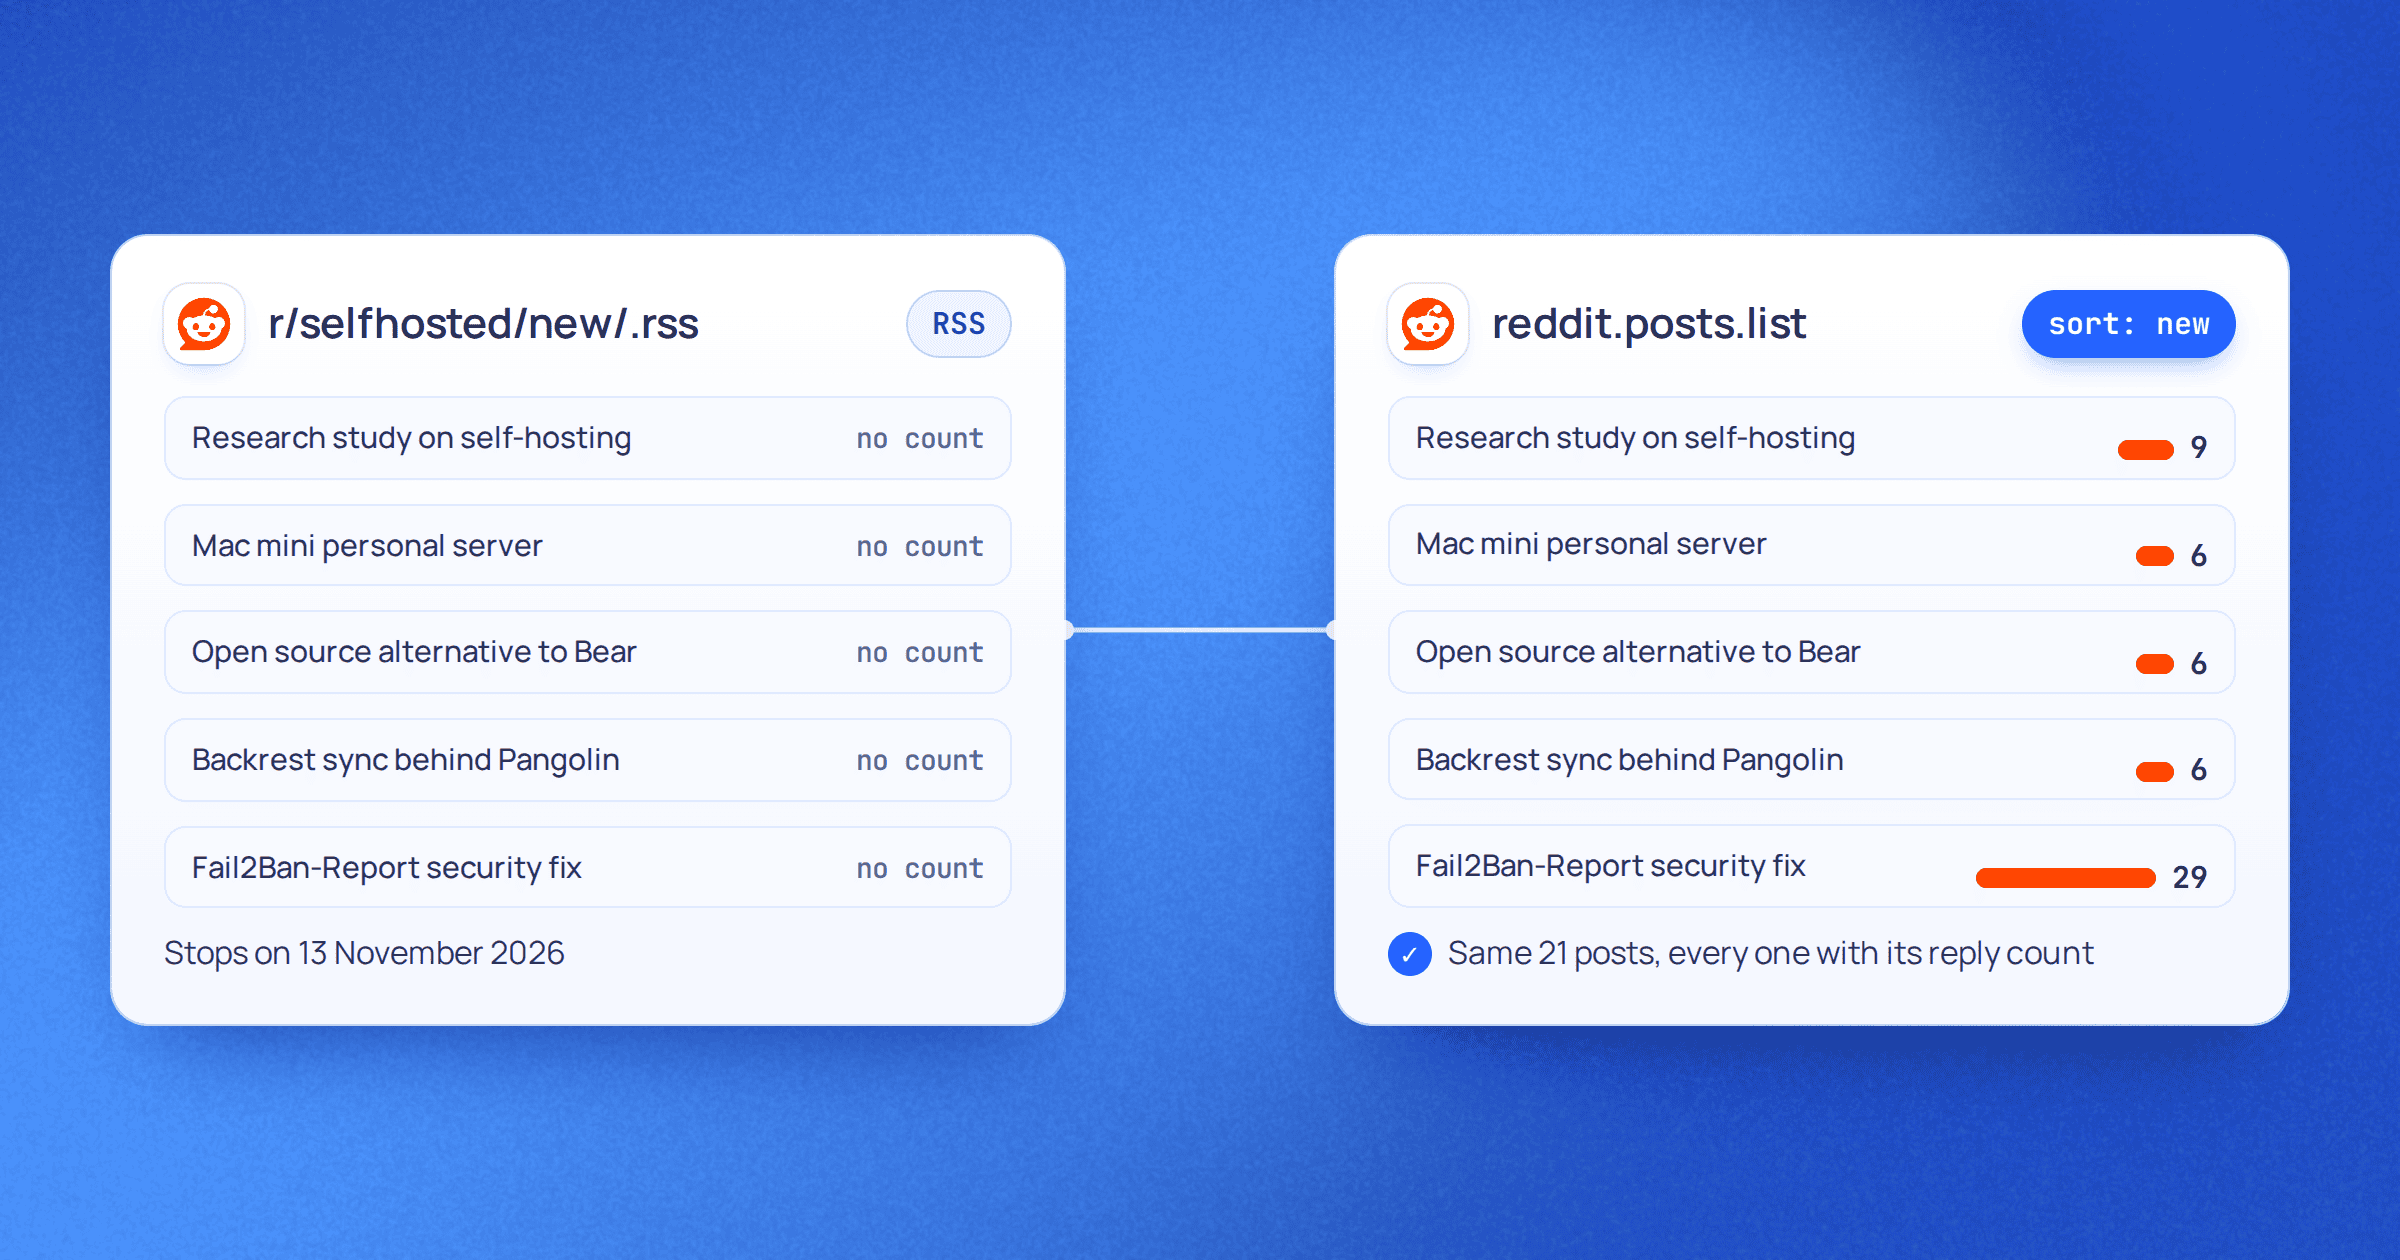
On November 2 we pulled r/selfhosted twice, a few seconds apart: once from its RSS feed and once from the endpoint, sorted by new. We compared the 21 newest posts. They were the same 21, in the same order. Fittingly, one of them was someone sharing a self-hosted RSS reader they'd built.
The difference was in what came with each post. RSS gave a title, link, author, time and text. It never said how many people had replied. The endpoint did, for all 21:
- Research study on self-hosting 9
- Mac mini personal server 6
- Open source alternative to Bear 6
- Backrest sync behind Pangolin 6
- Fail2Ban-Report security fix 29
- Server fleet manager (Spanish) 2
- VidLock media server 23
- Demand for self-hosted apps? 20
- Drawing app for kids 2
- Email vs WhatsApp vs fmsg 3
- Removing reading history 2
- Anubis with Apache vhosts 6
- Game hosting for friends 13
- CI on one €99 server 3
- Claude/ChatGPT to self-hosted apps 30 busiest
- P2P sync instead of Syncthing 15
- Buy a server or reuse a PC? 19
- Getting started 10
- Media stack diagram 15
- Simple Feed Reader (RSS reader) 4
- Humble home server ideas 15
Source: Upscrape reddit.posts.list, subreddits selfhosted, sort new, 2 November 2026.
The busiest new post was a question about letting Claude or ChatGPT reach self-hosted apps, with 30 replies. The quietest had 2. Upvote scores came back too, but on posts a few hours old they're mostly 0 or 1, so the reply count is the signal worth having. It's the one thing a rebuilt feed does better than the old one.
The script
It's about 60 lines of Python. Set UPSCRAPE_API_KEY to a key from the console, then run python subreddit_feed.py selfhosted. It writes selfhosted.xml, and each entry's summary starts with its points and reply count.
"""Rebuild a subreddit's "new posts" feed as an Atom file you can serve to any reader."""
import os
import sys
from datetime import datetime, timezone
from xml.sax.saxutils import escape

import requests


def fetch_posts(subreddit, limit=25):
    response = requests.post(
        "https://data.upscrape.com/execute",
        headers={
            "Authorization": f"Bearer {os.environ['UPSCRAPE_API_KEY']}",
            "Prefer": "wait=30",
        },
        json={
            "capability": "reddit.posts.list",
            "input": {"subreddits": subreddit, "sort": "new", "limit": limit},
        },
        timeout=70,
    )
    response.raise_for_status()
    return response.json()["results"][0]["data"]["items"]


def iso(ts):
    return datetime.fromtimestamp(ts, tz=timezone.utc).isoformat()


def build_feed(subreddit, posts):
    posts = [p for p in posts if p.get("id") and p.get("permalink")]
    updated = iso(max(p["created_utc"] for p in posts)) if posts else iso(0)
    entries = []
    for p in posts:
        stats = ""
        if p.get("score_available") and p.get("num_comments_available"):
            stats = f"{p['score']} points, {p['num_comments']} comments. "
        entries.append(
            "<entry>"
            f"<id>{escape(p['id'])}</id>"
            f"<title>{escape(p['title'])}</title>"
            f'<link href="{escape(p["permalink"])}"/>'
            f"<updated>{iso(p['created_utc'])}</updated>"
            f"<summary>{escape(stats + (p.get('body') or '')[:500])}</summary>"
            "</entry>"
        )
    return (
        '<?xml version="1.0" encoding="utf-8"?>'
        '<feed xmlns="http://www.w3.org/2005/Atom">'
        f"<id>https://www.reddit.com/r/{escape(subreddit)}/new/</id>"
        f"<title>r/{escape(subreddit)}: new posts</title>"
        f"<updated>{updated}</updated>"
        + "".join(entries)
        + "</feed>"
    )


if __name__ == "__main__":
    sub = sys.argv[1] if len(sys.argv) > 1 else "selfhosted"
    with open(f"{sub}.xml", "w", encoding="utf-8") as f:
        f.write(build_feed(sub, fetch_posts(sub)))
print(f"wrote {sub}.xml")We ran the feed-building half on that same November 2 pull and got a valid Atom file with all 21 posts in it. The request half is the call from our docs, unchanged.
Put it on a timer
Your reader needs a URL, so the file has to live somewhere it can fetch: a home server, a small static host, or the box that already runs a self-hosted reader like FreshRSS or Miniflux. Then let cron run it. Once an hour is plenty for most communities:
0 * * * * cd /path/to/feeds && python subreddit_feed.py selfhostedEach run is one call at 1 credit, and a failed call costs nothing. Hourly works out to 24 credits a day, about 720 a month for one subreddit. A slow community that only needs checking every six hours is about 120 a month. New accounts start with up to 100 free credits, enough to live with it for a few days before deciding, and pricing has the packs after that.
If you'd rather ask an AI agent "anything new in r/selfhosted?" than run a cron job, the same endpoint works over MCP. Our guide to web scraping with an AI agent covers when that's the better fit.
What it won't do
It reads public posts only, what a logged-out visitor can see, so private communities are out. It gives you new posts, not comments: the reply counts tell you where the conversation is, but to read it you open the thread. And it reads Reddit's public pages, so it depends on Reddit too. If Reddit changes those pages, every tool built on them, ours included, has to change with it.
Upscrape isn't affiliated with Reddit, and what you do with Reddit content is still covered by Reddit's own terms.
Before the 13th
Search your reader for reddit.com and go feed by feed. The subreddit feeds you can keep with the script above. For the rest, find the topic somewhere else, follow the people where they post, and save whatever you'd miss. Feedly isn't a way around it anymore, so don't wait on that.